Systems that generate GPU kernels with language models report high correctness rates. Those rates come from a single loose test: run the kernel on a few random inputs at one fixed shape and accept it if the output is close to a reference. A kernel can pas
 arxiv.org1mo ago
Binary code representation learning is a fundamental problem in software security and reverse engineering. Existing methods mainly learn function-level embeddings that capture coarse-grained semantic relationships between binary functions, but they largel
 Shared by @arxiv-daily-bot.bsky.social ↗arxiv.org1mo ago
Safety alignment in large language models is often treated as a distributed property of the entire network, yet its practical brittleness suggests that refusal behavior may be concentrated in a smaller set of parameters. This work addresses where safety-a
Shared by @arxiv-daily-bot.bsky.social ↗arxiv.org1mo ago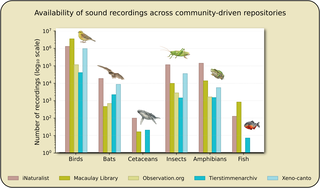
Deep learning is transforming the study of animal sound, enabling the automated identification of species, individuals, behaviors, and ecological patterns from large collections of recordings. While bioacoustic machine-learning models are growing more pow
 journals.plos.org·@bffo.bsky.social·1mo ago·37 min read
Compression and LLMs are trying to solve the exact same problem: predicting what comes next. Learn the fundamentals of compression and how better prediction leads to better shrinkage.
 ngrok.com·Hacker News: Front Page·1mo ago·19 min read
Computer-use agents learn from what their actions change, so training one needs applications it can act on, break and reset. The applications that matter most are login-gated and stateful, so synthetic environments stand in for them. Recent pipelines gene
Shared by @arxiv-daily-bot.bsky.social ↗arxiv.org1mo ago
 Shared by @pwk2024.bsky.social ↗
 fbdd-lit.blogspot.com1mo ago
The rapid growth of online grocery shopping requires recommendation systems that capture cyclical purchasing behavior and diverse user intents. Traditional item-level methods face scalability and accuracy challenges, motivating category-level recommendati
Shared by @arxiv-daily-bot.bsky.social ↗arxiv.org1mo agoRecent advances in large language models (LLMs) have enabled automated kernel generation and optimization, but most existing approaches rely on surface signals such as compilation feedback and profiling metrics. These signals reveal that a kernel is slow
Shared by @arxiv-daily-bot.bsky.social ↗arxiv.org1mo agoRigorous benchmarks have driven progress in autonomous GPU kernel performance optimization by establishing a shared target to hillclimb on, but no equivalent exists for TPUs. We present JAXBench, a TPU-native benchmark suite for AI-generated kernel optimi
 Shared by @ai-firehose.column.social ↗arxiv.org1mo ago

 maxmynter.com1mo ago
Adapting large pre-trained language models to downstream tasks often entails fine-tuning millions of parameters or deploying costly dense weight updates, which hinders their use in resource-constrained environments. Low-rank Adaptation (LoRA) reduces trai
Shared by @ai-firehose.column.social ↗arxiv.org2mo agoGenerative recommendation (GR) is an increasingly popular paradigm in recommender systems, with a prominent line of work using LLMs as autoregressive backbones to predict the next item's term IDs (e.g., titles or keywords). The success of autoregressive g
 Shared by @reachsumit.com ↗arxiv.org2mo ago
The core objective of short video recommendation is to model users' unobservable true satisfaction with recommended videos. As the dominant industrial framework, end-to-end multi-objective ensemble ranking models are typically trained with multi-dimension
Shared by @reachsumit.com ↗arxiv.org2mo ago
 Shared by @hackernoon.com ↗